- 25 Posts
- 27 Comments


 2·6 days ago
MoE models are flexible, see my guide for llama.cpp https://lemmus.org/post/24235317
Now there’s also
--moe-cache-mibthat could beat--n-cpu-moedepending on your exact hardware. I’ll need to write an updated guide.And now there’s Strata and PolyStrata which get even better performance than that.
 161·6 days ago
I just use llama.cpp with Zoo Code, the VSCode extension
join us !localllama@sh.itjust.works
It’s a MoE model so it’s much more flexible than a dense model, see my guide for llama.cpp https://lemmus.org/post/24235317
Now there’s also
--moe-cache-mibthat could beat--n-cpu-moedepending on your exact hardware. I’ll need to write an updated guide.And now there’s Strata and PolyStrata which get even better performance than that.


https://piefed.social/comment/13343280
PieFed has the concept of silencing another instance. A silenced instance is not defederated from but their posts do not show in the Popular or All feeds and their communities are not shown during onboarding. Their communities can still be found in the communities list (if you unblock the instance first) and joined in the normal way. Once joined, posts in there show up in the Subscribed feed of the joiner as usual.
Since I added silencing functionality I feel like there’s almost no need for (more) defederation. I can offer protection to newbies who don’t yet know which places to avoid and they can explore the dark corners when they’re ready. It’s a low-drama way to put a bit of distance between groups that rub each other the wrong way.
Yeah default blocks or silencing or something like that
PieFed allows admins different levels of blocking instances, they can do defederation but there are levels softer than that
oh yea feddit blocks shitjustworks https://feddit.online/instance/sh.itjust.works/posts
maybe @xSikes@feddit.online could ask their admins to convert the defederation to a “silenced” or whatever that feature is on PieFed
32GB RAM, RTX 2080 8GB VRAM, I use Tiel Coder 35b-a3b (it’s a fine tune of Qwen 3.6) with Zoo Code
I see the last activity was 2 months ago.
that means no one from your instance is subscribed, if you subscribe then you’ll get new posts
you can see that there are new posts here https://sh.itjust.works/c/localllama



maybe it’s better than Qwen 3.6 35b a3b?
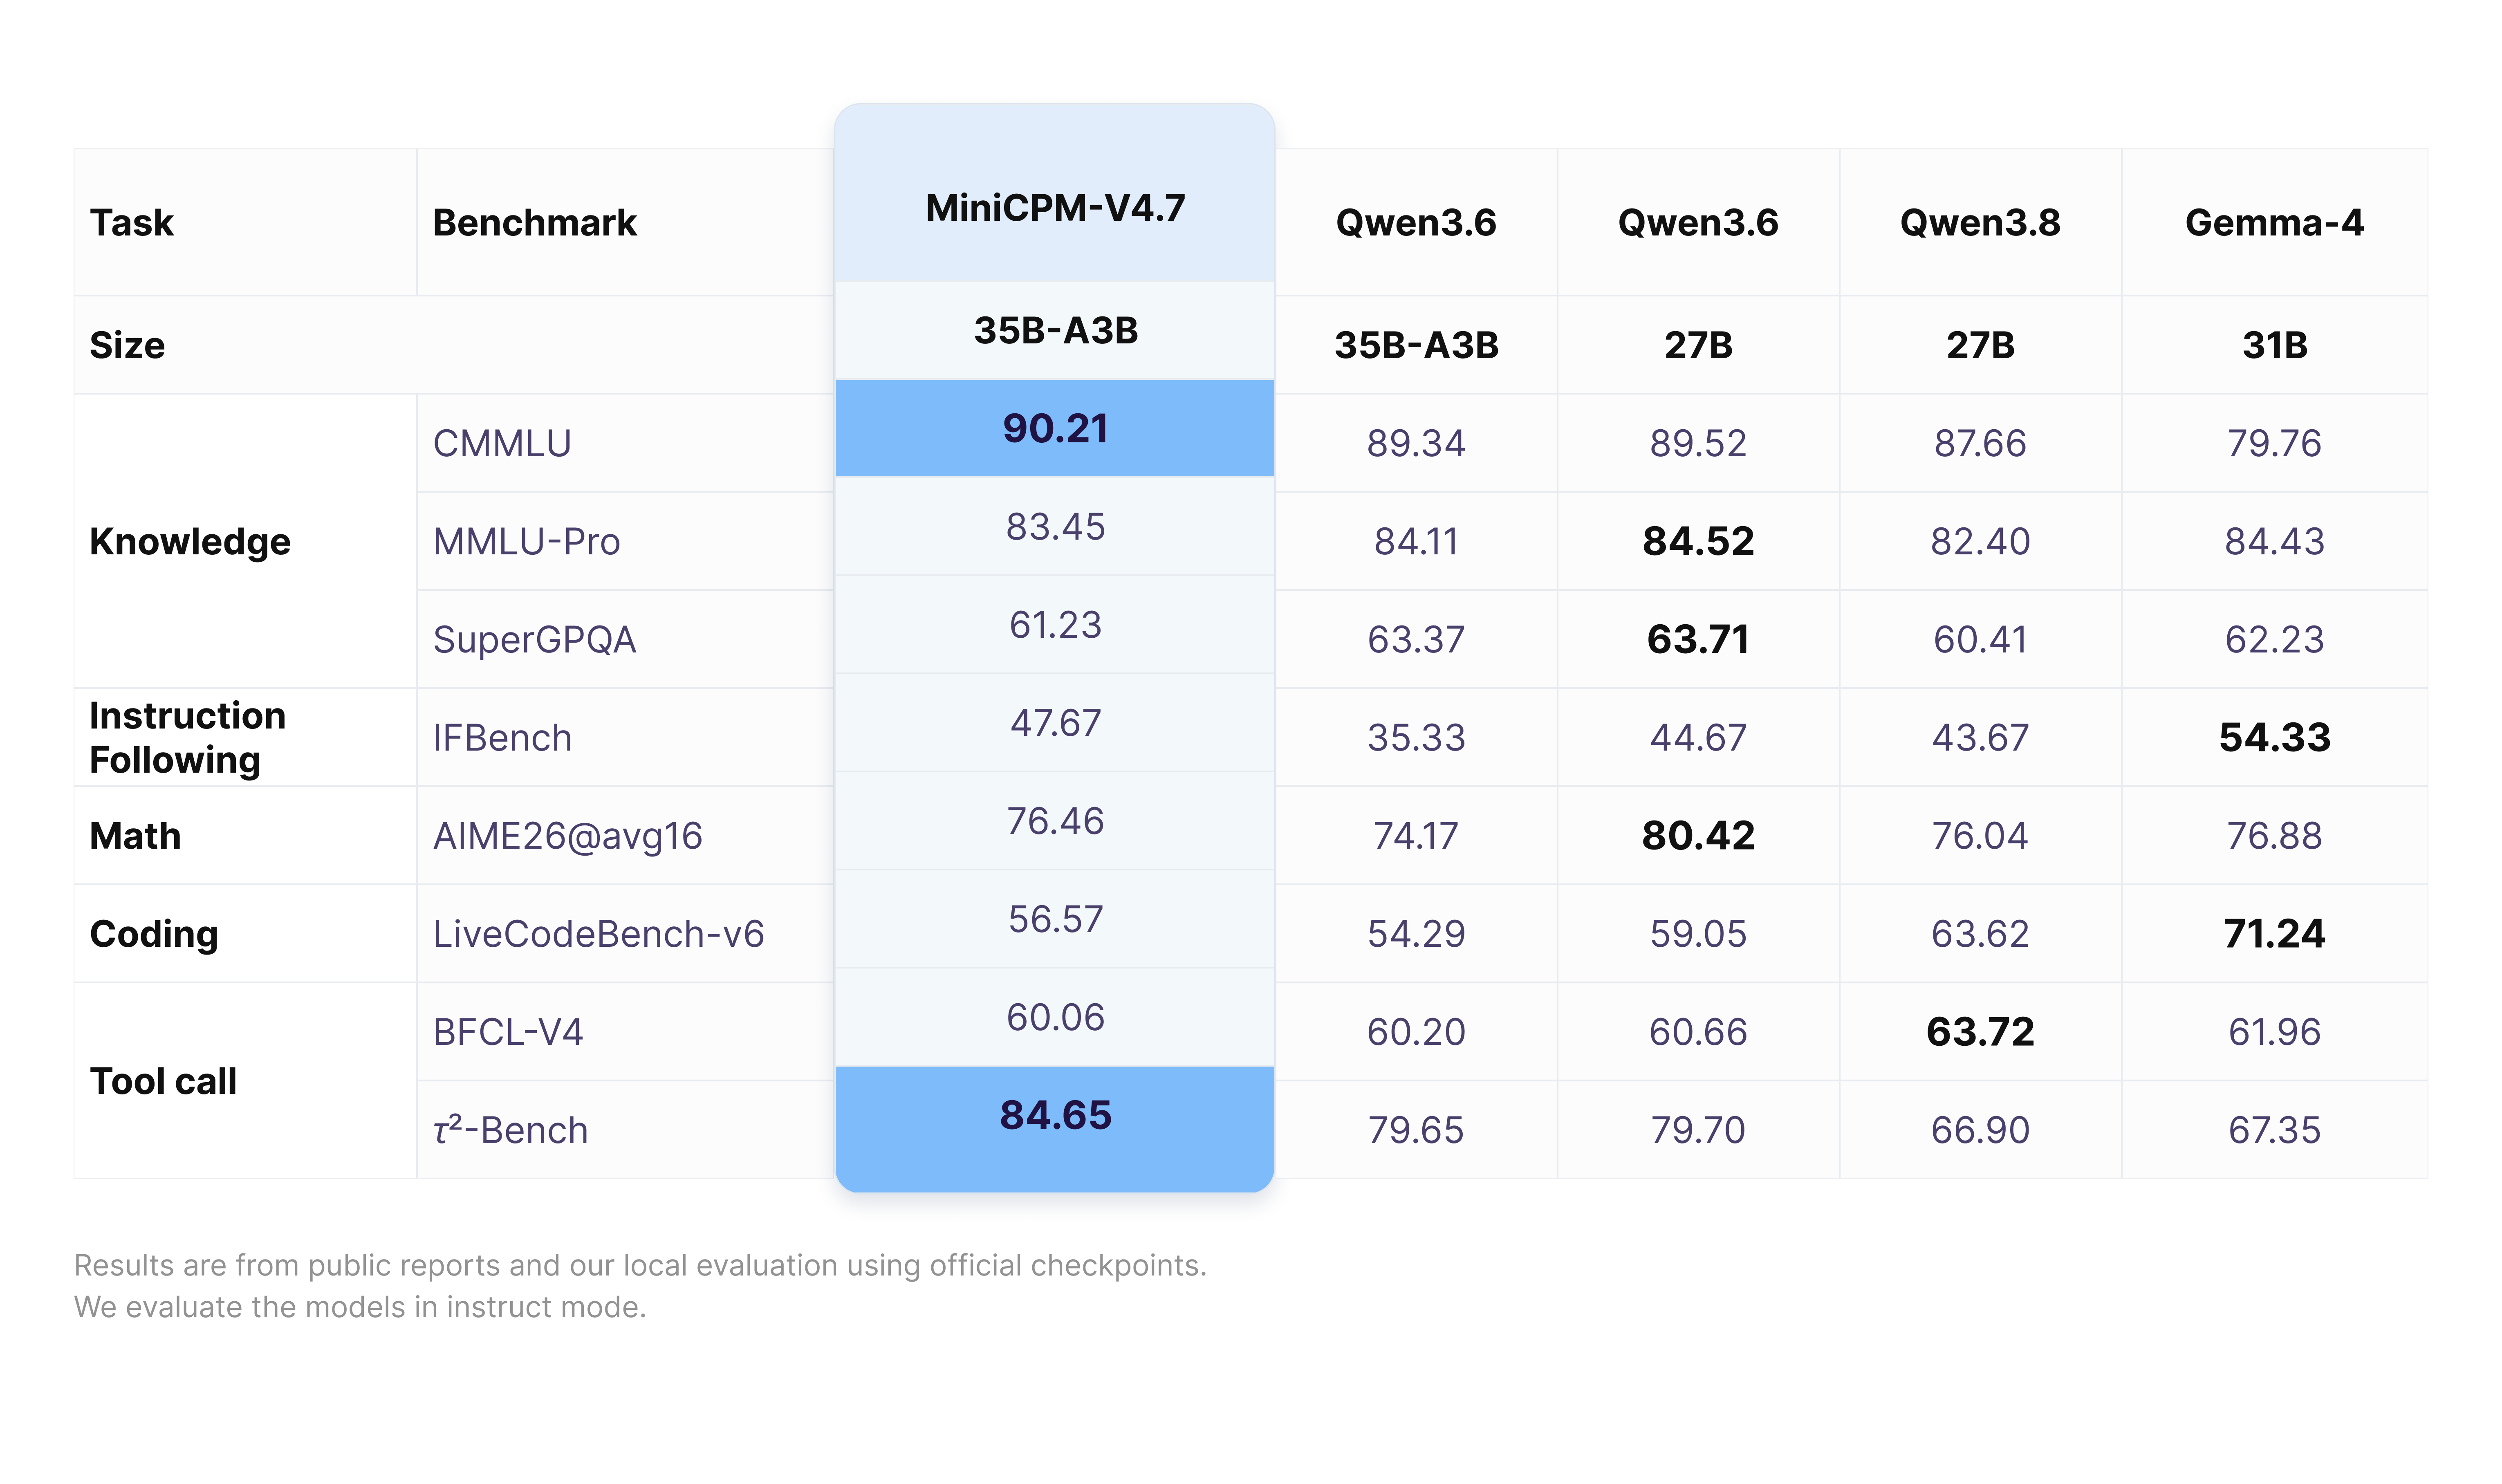

If they can make the KV cache size scale more efficiently with many tokens, like DeepSeek 4.1 Flash fitting 1 million tokens in 890MB, it might give them enough room to add a couple billion parameters of weights and still fit well in 32GB GPUs
Yeah it’s a really nice size for older gaming computers. Of course it can still be beaten by smaller models from other labs, so that kinda defeats the purpose, but it’s nice in theory
32GB RAM and 8GB VRAM here, so 35b a3b is about my maximum, maybe with added n-grams

Is it better than Ling Tiny 3.0 8b-a1b?

I’m pretty disappointed this one was merged, it doesn’t give good performance.
I haven’t yet understood completely the details, so can’t provide much info or suggestions for improvement yet.
Should be good to merge and iterate on it from master.
WHAT? Why did they choose to merge this one out of many if they don’t even understand it?
I was getting way better performance with the old PR from miltos22 https://github.com/ggml-org/llama.cpp/pull/26563
This is quite a comment someone left in one of the PRs lol
@am17an if 1000 line PR is too much of a scope for a project, the project is fubar. is llama project so broken it can’t handle 1000 line PRs? state so publicly, so that the community can stop wasting time contributing to a project like that and move on.
The one they accepted was nearly 1000 lines anyways.


you can subscribe to !hackernews@lemmy.bestiver.se and then cross-post to here when appropriate
I have a guide for performance tuning that should be a pretty good start
https://lemmus.org/post/24235317
Let me know if you have questions, or maybe just make a post asking how to optimize for your hardware and I’ll try to answer
I would suggest you don’t use Ollama https://sleepingrobots.com/dreams/stop-using-ollama/ If you want a GUI, Unsloth Studio is probably best and open source. LM Studio is good too but closed source.
I just use llama.cpp llama-server with the built-in Web UI
Also check the llama.cpp docs
https://github.com/ggml-org/llama.cpp/blob/master/tools/cli/README.md
I would guess writing the reason is the same thing as a model’s internal reasoning, it just increases accuracy of responses. Not sure about your other questions, that would need some specific tests
it wouldn’t be that slow since you’d just need to output a few tokens, or even just 1 token if you label the choices as A, B, C, D…


what are the specs? Try Ling 3.0 Tiny, that’s probably the fastest decent model, it should be both smarter and faster than Qwen 3.5 4b